We didn't need a better model. We needed a better harness.
When an agent gets it wrong, the first instinct is to buy a bigger model. Most of the time the real fix is in the tools, context, memory and checks around it.
Someone asks the agent a question in Slack. A few seconds later the answer arrives. It is confident, nicely formatted, with a bold number and a short summary.
And it is wrong.
The first instinct in the room is always the same: we need a better model. Sometimes that helps. Most of the time, the problem is not the model. It is the harness.
A strong horse is not enough
Picture a big draft horse. Huge power. Without a harness, it cannot pull a single cart.
Give it a bad harness and it is worse. The straps rub, the load pulls to one side, and all that strength goes in the wrong direction.
AI agents work the same way. The model is the brain. The harness is everything around it: the code that decides what the model sees, what it can do, what it remembers and how its work gets checked.
Two teams can use the exact same model and get very different results. The only difference is the harness. In my work, that is where most of the engineering happens.
What the harness actually is
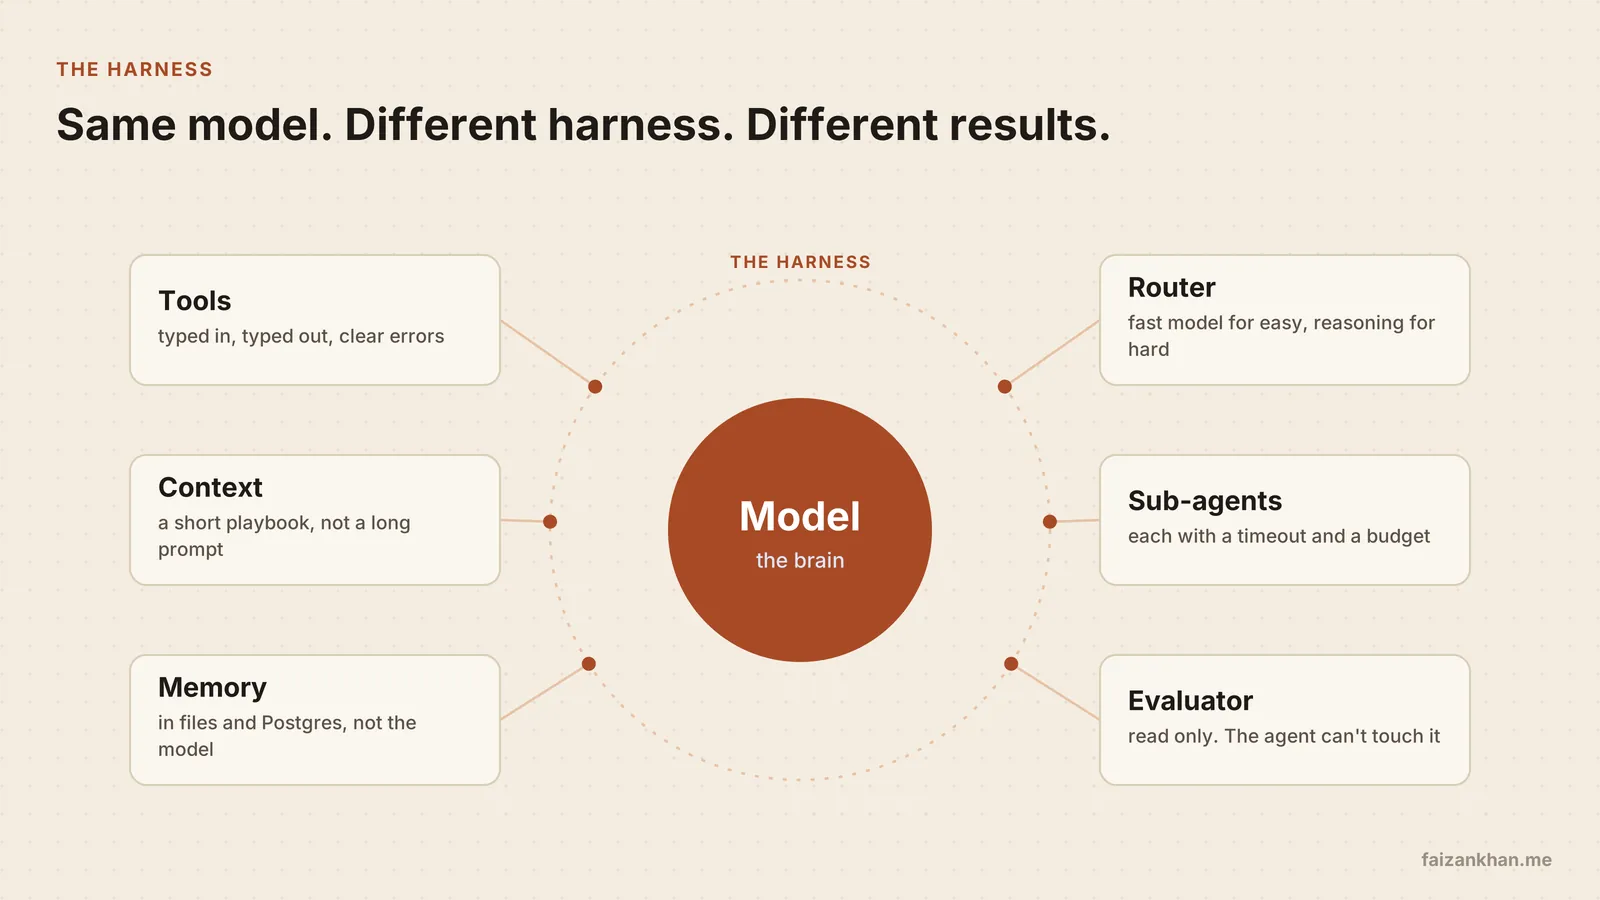
I build agents that people use from Slack and that run as steps inside Airflow pipelines, on Google Cloud. Across those projects, six parts of the harness matter most.
1. Tools with typed contracts
A tool is a function the agent can call, like "query the warehouse" or "search the docs". Every tool gets a typed input, a typed output and a clear error. Typed means the shape is fixed and checked, for example with Pydantic models.
I write tools so I can test them without any model involved. If a tool is flaky, no prompt will save you.
2. Context as a short playbook
The context is everything the model reads before it answers. It is tempting to add a new rule to the system prompt every time something breaks.
I have felt that pull myself, because it feels like progress. It is not. After a few months the prompt is long, full of rules that contradict each other, and expensive on every call. So I keep a short, curated playbook of lessons instead. I delete old entries as often as I add new ones.
3. Memory outside the model
Long tasks do not fit in a context window, the limited amount of text a model can read at once. So logs, intermediate results and error traces go into files or Postgres. The agent reads only what it needs.
A bonus: when a run crashes, it can continue where it stopped instead of starting over.
4. A router
Not every question needs a slow reasoning model. A router sends easy requests to a fast, cheap model. Hard, multi-step problems go to a reasoning model with a capped budget, so it cannot think forever on your bill.
This one decision often cuts cost more than any other change.
5. Sub-agents with limits
Independent subtasks can run in parallel helpers, called sub-agents. Each one gets a timeout, a budget and a fixed return format. Without limits, parallel agents become parallel bills.
6. An evaluator the agent cannot touch
The evaluator is what scores the agent's work. It must be separate and read-only. If the agent can influence its own grade, it learns to please the grader instead of solving the task.
A typical failure: the half-read table
Here is the kind of failure I mean. It is the most common one I see.
Someone asks for last quarter's revenue. The agent calls the warehouse tool. The query returns 2,400 rows. That is more than fits in the context window, so the result gets cut off and the model only sees the first 1,000 rows.
The model does not know anything is missing. It adds up what it sees and writes a clean, confident answer. Less than half the truth, presented as the whole truth.
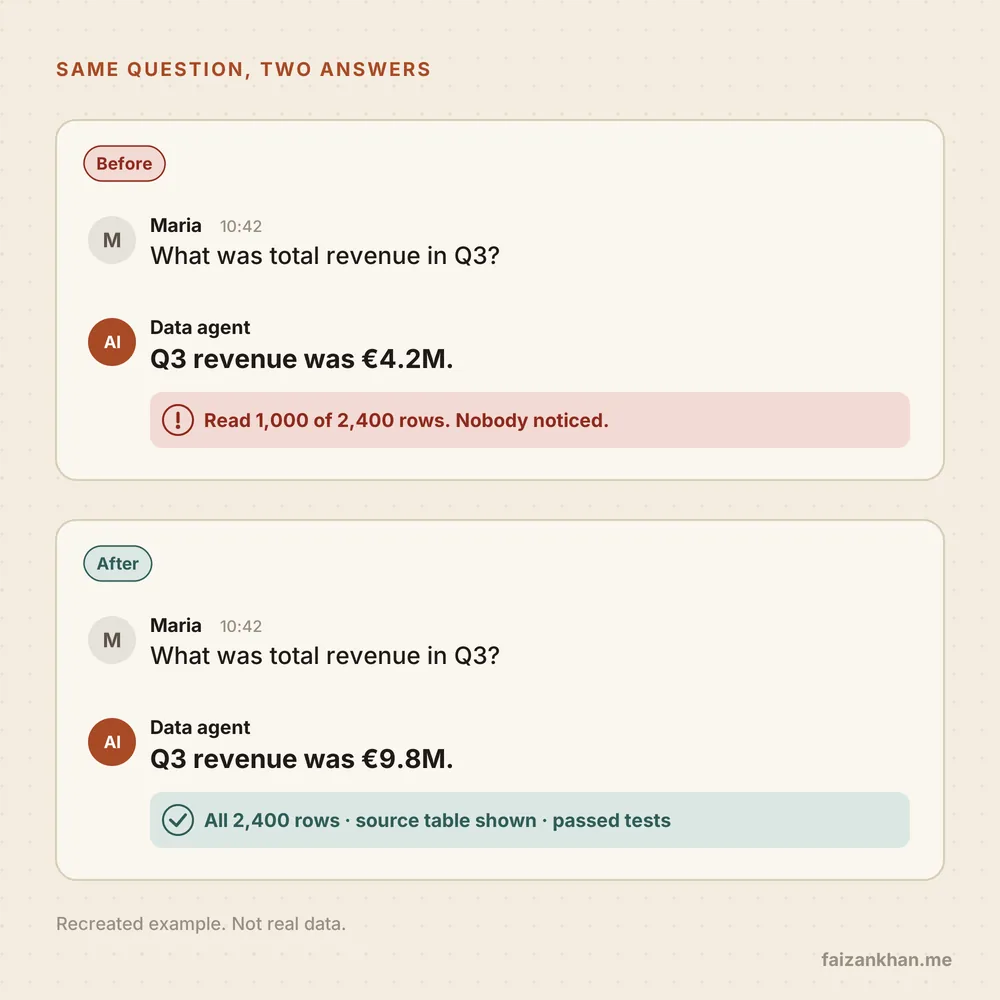
A bigger model would not fix this. A bigger model would just write a more convincing wrong answer. The fix is in the tool:
- Do the maths in the tool. Aggregate in SQL. The warehouse is good at
SUM. The model should get one number, not 2,400 rows. - Set row limits. If a query would return too much, the tool says so instead of quietly cutting the result.
- Paginate when you need detail. Let the agent ask for page 2 on purpose, so it knows there is a page 2.
- Fail loudly. "Result truncated: read 1,000 of 2,400 rows" is a useful error. Silence is not.
- Keep it read-only. The warehouse tool uses an account that can read and nothing else. A confused agent cannot drop a table.
I wrote more about running tools as separate, locked-down services in Running AI agents on Google Cloud.
The model was not wrong. It answered the question it was given. The harness gave it half the data.
How the harness gets better every week
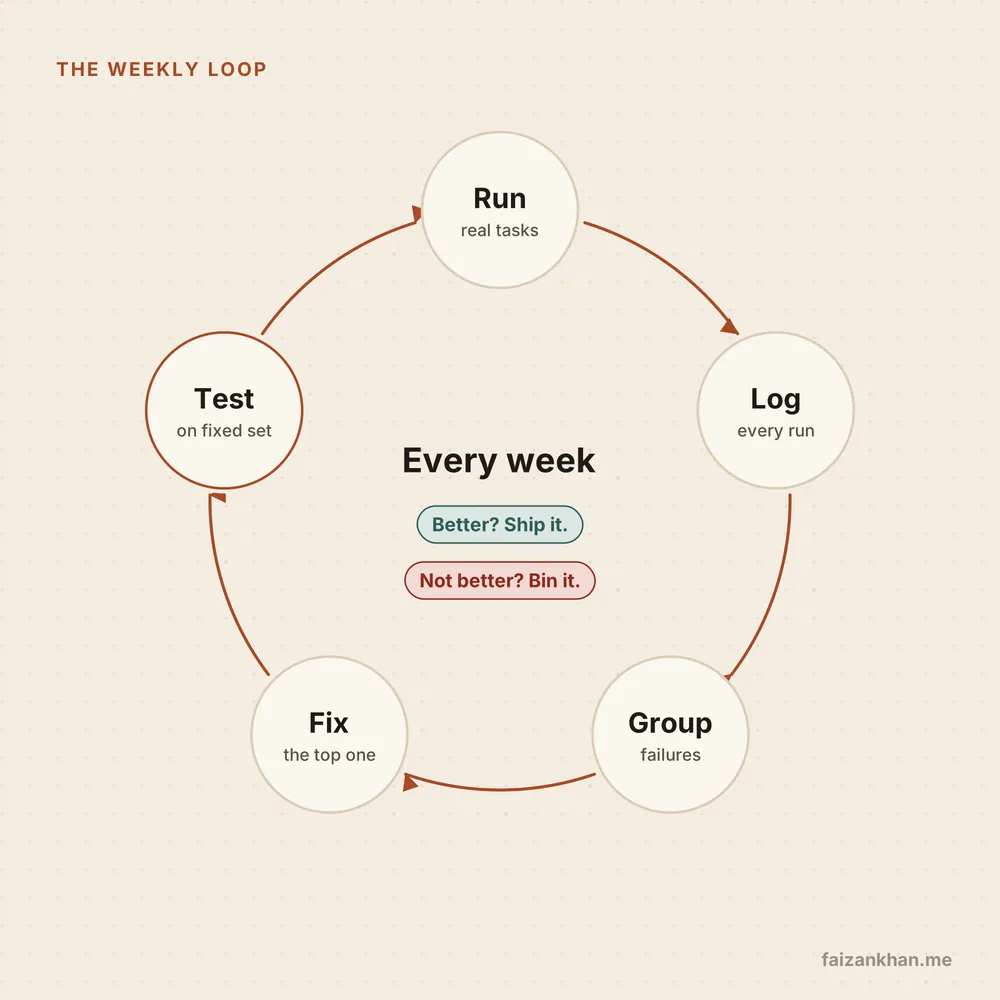
The most useful habit I know is a boring one: read the failures.
Run the agent on real work. Log every run as a trace: each tool call with its input, output and duration. When someone asks why the agent said something, the trace is your only real answer.
Once a week, group the failures into patterns. Most bad answers fall into a handful of buckets. Then fix the most common one. Just one.
Finally, test the fix against a fixed eval set: a stable list of real tasks with known good answers. If the new version beats the current one, ship it. If not, bin it, even if it felt like a good idea.
This is continuous integration, applied to agents. Every change is a pull request that has to earn its place.
Research teams now run this loop automatically, with one model proposing changes and another testing them. For most companies, the manual version is already a big step up. It also keeps a human in charge of what ships.
Change one thing at a time, and only keep what the evals prove.
What I would tell you
- Check the harness before the model. Look at the tools, the context and the evals first. A new model is the last thing to try, not the first.
- Make tools strict. Typed inputs and outputs, read-only access, row limits and loud errors. Aggregate in the tool, not in the model.
- Keep the prompt short. A curated playbook beats a growing wall of rules. Long state belongs in files or Postgres.
- Route by difficulty. Fast models for easy work, reasoning models with a budget cap for hard work.
- Put limits on everything that runs in parallel. Timeout, budget and return format for every sub-agent.
- Run the weekly loop. Log every run, fix the top failure, and ship only what beats your fixed eval set.
Working on something like this?
Tell me what you are building and where you are stuck. I will tell you honestly if and how I can help. Or email hello@faizankhan.me.
Muhammad Faizan Khan is an AI and data engineer in Berlin. He builds AI agents, data platforms and the software around them. More about me.