Moving to a lakehouse without stopping the business
Reports still go out on Monday, even mid-migration. Here is how I move old pipelines to a lakehouse step by step, so nobody notices the switch.
It is Friday afternoon. Finance asks if the revenue report will be ready on Monday. You are halfway through moving the data platform, and the honest answer is "probably".
Nobody wants to hear "probably" about revenue.
That feeling is why I care more about how a migration runs than about where it lands. Here is the method I use to move old pipelines to a lakehouse while the business keeps working.
Why migrations fail
Most migrations do not fail because of technology. Spark works. S3 works. The new tools are fine.
They fail because the business cannot pause. Reports go out on Monday. Sales wants its pipeline numbers every morning. Operations runs on a dashboard someone built five years ago.
So the team tries a "big bang": build everything new, then switch over one weekend. The switch slips. The numbers do not match. People lose trust in both systems at once.
The goal is not a fast switch. The goal is a switch nobody notices.
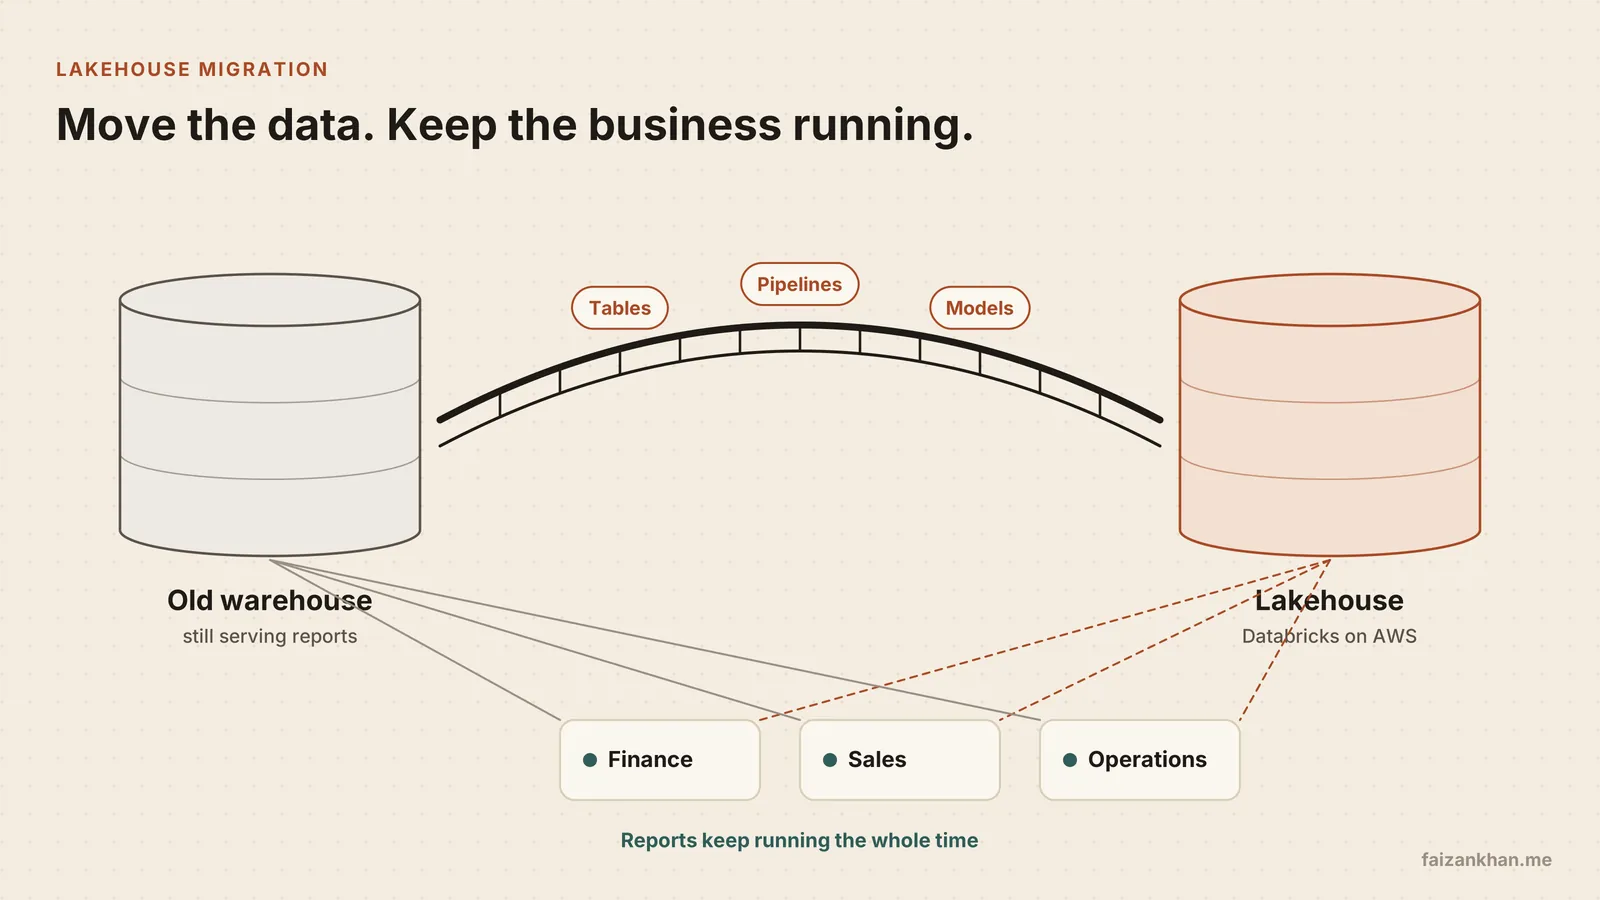
What a lakehouse is, in plain words
A lakehouse keeps your data as files in cheap object storage, like Amazon S3. On top of those files sits an open table format, such as Delta Lake or Apache Iceberg.
The table format is the clever part. It turns a folder of files into something that behaves like a real warehouse table. You get ACID transactions, which means a write either fully happens or does not happen at all. No half-finished loads.
The big win is one copy of data. Your BI dashboards and your machine learning work read the same tables. No second copy drifting out of sync somewhere.
The five phases
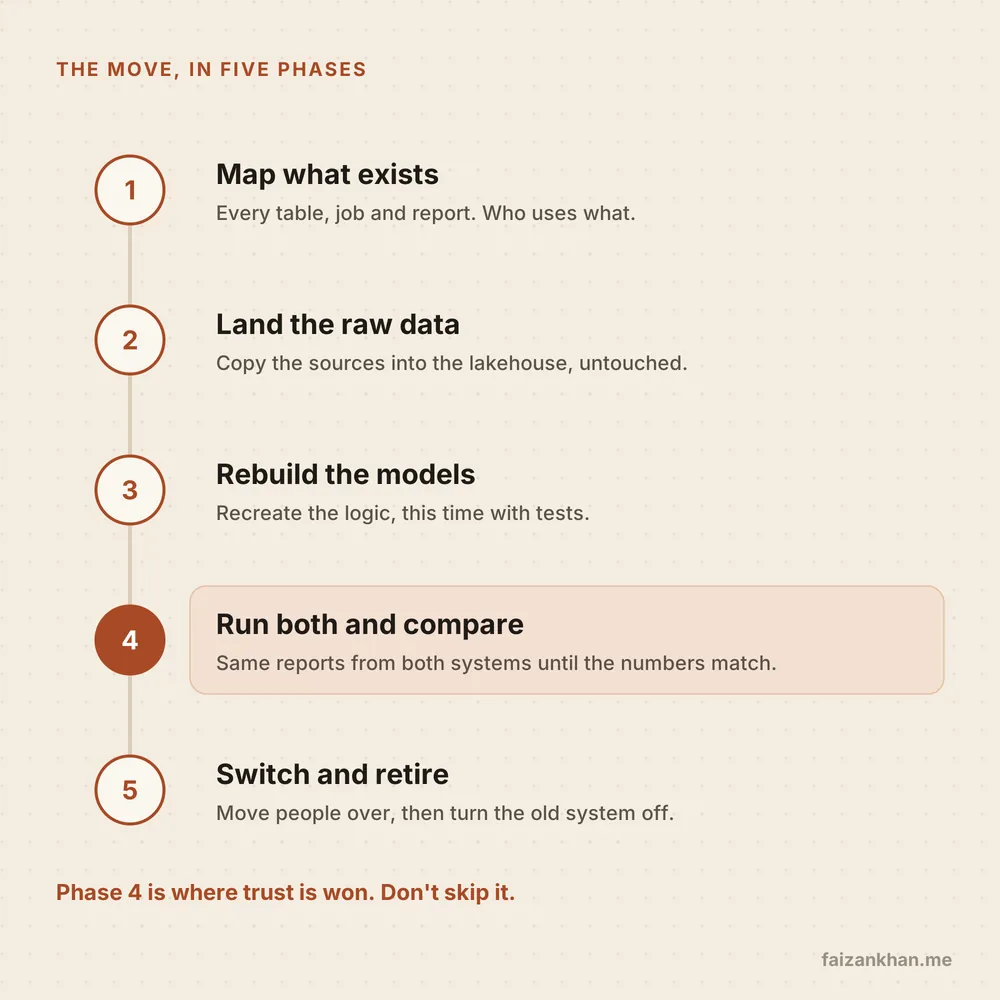
I split the work into five phases. They overlap a little, but the order matters.
Each phase has one clear question. What do we have? Is the raw data safe? Are the new models correct? Do the numbers match? Is everyone moved?
If you cannot answer the question, you are not done with the phase. That simple rule saves a lot of arguments later.
1. Map what exists
Start with an inventory. Every table, every job, every report. For each one, write down the owner, how often it runs and how often it fails.
This is boring work. It is also where you find the report that three people depend on and nobody knew about.
The failure rate helps you choose where to start. Pick something important enough to matter but simple enough to finish in a few weeks. An early win buys trust for the hard parts.
2. Land the raw data untouched
Copy data from the source systems into the lakehouse exactly as it is. No cleaning, no joins. This is the bronze layer.
Why untouched? Because when a number looks wrong later, you want to go back to the original and replay it. Raw data is your safety net.
3. Rebuild the models with tests
Now build the silver layer (cleaned, typed, deduplicated data) and the gold layer (business-ready tables that reports read). This bronze, silver, gold pattern is called the medallion architecture.
You can build these with dbt models or with Databricks jobs. What matters more is that every model has tests: no nulls where there should be none, unique keys, totals that make sense.
4. Run both and compare
I think of this phase as a canal lock. A lock lifts a boat from one water level to another. Nobody drains the canal to do it.
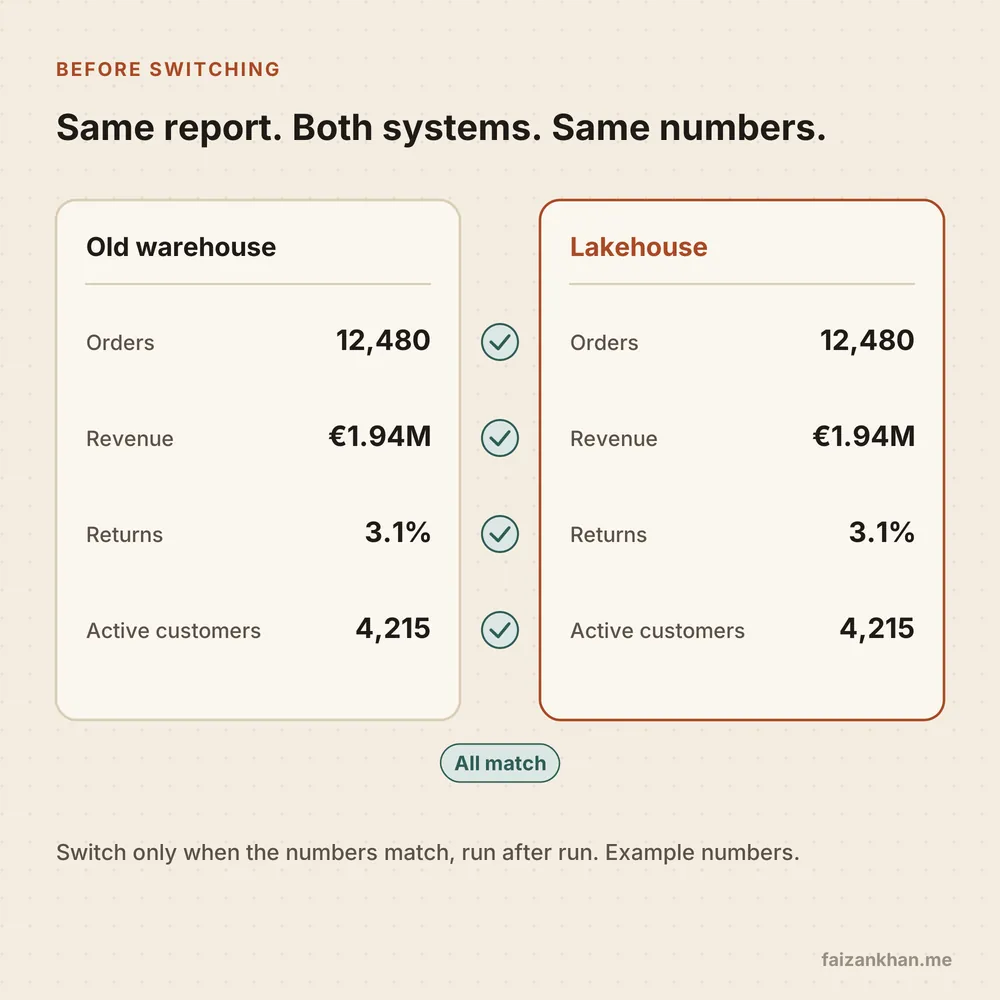
In data terms: the old and new pipelines run side by side on the same inputs. The old one still serves the real reports. The new one runs quietly next to it.
Every day, a reconciliation job compares them. It checks row counts, totals on the key columns and a sample of individual records.
When something does not match, you find out why. Often the old system was wrong, and that is a conversation you need to have with the business, not hide.
You keep this parallel run going until the numbers match run after run. Not once. Many days in a row, including month end.
5. Switch consumers, then retire the old system
Move dashboards and downstream jobs one by one. Each switch has an owner who looks at the new output and signs off. Finance signs off on finance reports. Not the data team.
Keep the old pipeline in read-only mode for a short time, as a fallback. Then turn it off for real.
This last step is the one teams skip. Leaving the old system running "just in case" is how you end up paying for two systems forever.
What this looked like at Hella Gutmann
At Hella Gutmann Solutions I led the BI and data warehouse team, and we moved our pipelines to Databricks on AWS this way. Step by step, with both systems running until the numbers matched.
We measured before and after. In the end we had about 60% faster data system performance. Having that number made every later conversation much easier.
The honest trade-off
Running both systems costs money. For a while you pay for the old warehouse and the new lakehouse at the same time. You also pay in patience, because the parallel run feels slow when everyone wants it done.
The temptation is to cut the parallel run short when the numbers look "close enough". I have felt that pull, and giving in to it is a mistake. Close enough on Tuesday becomes a wrong report at month end. A few extra weeks of double cost is cheap compared to losing the business's trust in the data.
The double cost is the price of a switch nobody notices.
What I would tell you
- Do not lift and shift bad models. A migration is the cheapest moment you will ever get to fix naming and logic.
- Measure before and after. Write down run times, costs and failure rates first. You will need them to prove the move was worth it.
- Train the people. A platform that only the data team understands is not finished.
- Infrastructure as code from day one. Use Terraform for workspaces, clusters and permissions, so every environment is built the same way.
- Set up permissions properly. Use Unity Catalog or a similar catalog so access rules live in one place, not in scattered scripts.
- Plan the shutdown date. Put the retirement of the old system on the plan from the start, with a date.
Working on something like this?
Tell me what you are building and where you are stuck. I will tell you honestly if and how I can help. Or email hello@faizankhan.me.
Muhammad Faizan Khan is an AI and data engineer in Berlin. He builds AI agents, data platforms and the software around them. More about me.